Wednesday, April 13, 2016

Simplify Big Data Testing through Spark library


Testing Big Data Pipelines is increasingly becoming complex. This has two factors. One is with maintaining setup and one is with defining or deriving the expected result.

Maintaining Setup
Hadoop ecosystem is growing rapidly and different teams are utilizing different components of ecosystem which suite their need. This increases number of components of Hadoop ecosystem to be maintained in Test Setup. This includes maintaining correct versions, required directories with correct ownership, local users and hdfs users, status of services. It is estimated that 60-70% of test cycle is vested on deployments and configurations.

Defining or deriving Expected Results
After setup the biggest challenge will be to figure out a substance with which the output is compared to. This substance is known as expected Result. There are different ways to do that. We will talk about 3 major variances.

  1. Golden Dataset
A predefined data set which is mostly hand woven and expected result is derived by going through the data manually.
  1. Production Dataset
This data is a subset of data copied from Production System. Expected result will be derived by running SQL, HQL or Pig Scripts that are hand written.
  1. Generated Dataset
This data is generated with variety of tools/programs with a predefined set of rules. Expected result will be derived by running the SQL, HQL or Pig Scripts that are derived by the tool/program.

Proposal
The proposed system will deal with these complexities by providing various REST Services like

  1. Infrastructure Service
This service provides APIs to deploy given set of machines with different components, configure and validate the deployments. Deploying, Configuring and Validating deployments are three independent services so that one can use them independently based on the kind of setup he has.
  1. Data Service
This service provides APIs to generate data, ingest data into HDFS with given rules. Generating data and ingesting data are two independent services so that one can use them based on their requirement.

  1. Execution Service
This service provides APIs to utilize various executors to run their Pipelines and monitor them. Again utilizing executors and monitors are independent. This service also provides APIs to retrieve performance related Metrics.
  1. Validation Service
This service provides APIs to invoke various validators based on the dataset.


Each service will use utility methods provided in a separate repository.

Utilities
Following utilities will be provided as part of this framework.

  1. SSH Utils
These will help to connect to a remote machine and execute commands on it. It also provides capabilities to transfer files from and to remote machine.
  1. Benerator Utils
These will help in generating data using Benerator tool, creating schema for HSQLDB and deriving expected results.

  1. Hadoop Utils
These will help in executing hadoop commands, copying files to and from hadoop.
  1. String Utils
These will help in dealing with all kinds of String operations.
  1. JSON Utils
These will help in dealing with JSON related complexities like getting value of a given element in a complex JSON, creation of JSON using objects.
  1. Database Utils
These will help in maintaining connection pool, connecting and executing and retrieving results from any Database using JDBC connector.
  1. lzo Utils
These will help in compressing and uncompressing files using lzop.
  1. Pig Utils
These will help in executing pig scripts, monitoring the execution.
  1. Falcon Utils
These will help in creating cluster, submitting feeds, submitting process and monitoring.
  1. Storm Utils
These will help in submitting Storm Topologies and monitoring them.
  1. Kafka Utils
These will help in start/stop/restart producer/consumer/Kafka server.
  1. Ambari Utils
These will help in deploying through Ambari blueprints, start/stop/status/restart of services and components, configuring services and components, sync configs from another cluster.
  1. RESTUtils
These will help in creating GET/POST/PUT REST requests, submit them and get results in JSON.

All utility methods should provide Java Documentation.

This framework will be provided as Hosted Service from Data QA Team. But the infrastructure to run the pipelines will not be a hosted service and should be registered with this framework while calling REST APIs.

Advantages

  1. Existing framework only works with in-memory dataset due to tight coupling of Benerator. With new design one can use any Dataset and any Validation.
  2. In the current system there is no way to test with production Dataset or Golden Dataset. With new design one can use any Dataset
  3. Current system cannot be used for Performance or Stability related testing as it works with in-memory dataset. With new design one can pump large data sets and can measure performance, stability or reliability of the platform.
  4. During a test cycle if one wants to use some operations available in the framework, he has to gather a lot of information to segregate that code and use. This will be taken care with the new design due to introduction of REST APIs.
  5. As this framework will be a Hosted Service, adaptability will be more and resistance will be less.


Implementation


Execution
mvn exec:java -Dexec.mainClass=<Fully_Qualified_Class_Name_Main_Method>
~Yagna

RestAPI Docs using apidocjs during build on Jenkins


* Installation - npm install apidoc -g


* Sample Documentation done for a Distcp(Hadoop File System) utility method is shown below


* Create a file called apidoc.json with following content

* Now in Jenkins  


* Now from the browser go to the workspace of this Project in Jenkins and see docs folder and point to index.html, you can see following icon
* Left side of the page will have 

* On Right side of the page shows actual documentation

* One can get more detailed examples at  http://apidocjs.com/

~Yagna

Tuesday, December 8, 2015

Testing in Agile Sprint using SuiTest (TestFlo)

Tim and Joe are members of an agile Team. Tim playing a developer role and Joe playing QA role. John is Scrum master. They are working in a Sprint of 2 Weeks. Let us illustrate several situations arises during a Sprint.


Tim: Hi Joe, coming for Sprint Planning meeting?
Joe: Yeah, let’s go.


Tim: Oh! Hectic meeting. But I am sure of what to deliver for this Sprint.
Joe: But tell me more about Story JTP-227.
Tim: Story on JIRA is updated with links where you can find more details. You can come back to me if you need more clarifications.
Joe: Thanks Tim.


Joe: Hi Tim. I have written Test Cases for Story JTP-227, can you review?
Tim: Sure! Where can I see Test Cases and how do I know which one is related to Story?
Joe: Test Cases are listed down under a Story in JIRA
Tim: Really!! I have never seen like that. Are they subtasks for Story?
Joe: No. They are not subtasks. They are Test Cases in JIRA. We are using a plugin called SuiTest. See here how they look

Tim: That’s awesome. Let me review and revert back by EOD.


Tim: Hey Joe, I have review and have put review comments for Test Cases in JIRA.
Joe: Sure I will look into them.


Tim: Hey Joe, just want to check what's the status of Test execution for Story JTP-227.
Joe: 1 sec, let me open JIRA to see Test Execution status for Story … Okay here is the status. Executed 2 Test cases out of 3, 1 Pass, 1 Fail.

Tim: Is JTP-235 failing? What the Bug id?
Joe: JTP-238. You can find Bug ID against failed Test Case.
Tim: Cool! That made it easy for me to understand the steps with which I can reproduce the issue. I can execute this test case to verify my Fix.

John: Hi Joe, what the status of Test execution for Release.
Joe: Hi John. What a pleasant surprise! One sec, I will open JIRA to check Test Execution Status of Test Plan for Release X.
Okay here it is. We have executed 67% and there is one Open Bug JTP-238.
John: That’s a quick answer. Thanks Joe. I am going for lunch. Bye.


John: Hey Joe, are all the test cases written by you ported to JIRA?


John: One last question, I can see that there are 267 regression tests, do you run all of these and update on JIRA? It will take a lot of time to do this right?
Joe: No John, we don’t update JIRA manually, we use JIRA API to run Automated Tests and update JIRA automatically.


From above illustrations we can understand the following benefits

  • Building repository of Test Cases allowing you to create Test Plans
  • Snapshots of test cases within Test Plan or Story
  • Establish real-time insights  and clear traceability between requirements, test cases, and defects to determine test coverage and ensure tests exists for all requirements.
  • JIRA Software integration and Sprint reports
  • Import Test Cases from CSV, TestLink and other systems
  • Run automated tests on Bamboo/Jenkins by changing the status of your Test Plan and receive updates about the results of tests execution in JIRA using comprehensive REST API
  • Plan, track, and proactively manage manual, automated, and API tests in one repository to mitigate risk.
  • Use reports to get better understanding of test coverage, defect trending, and sprint status.

Image Courtesy: Images are taken from https://intenso.atlassian.net/wiki/

Monday, April 27, 2015

Traceability Matrix using TestLink/github and Jenkins/Hudson

               At my current work place we were using TestLink (We have moved to SuiTest now) for writing TestCases and my boss asked me to see if all the Stories have Test Cases or not. I have written this simple program and integrated with Jenkins to get a nice graph showing Test Case traceability like below


In the above graph red line shows total Stories in a sprint, green line shows Stories which have at least one Test Case and blue line shows stories which have at least one automated test case.

To achieve this we have followed below rules as a Team.


  1. Test Suite in TestLink has same name as Story ID in JIRA
  2. Test Suite Name in Java/Script in github has same as Story ID in JIRA
This traceability program takes stories in a Sprint as input and do following things
  1. Connects to TestLink and searches for Test Suites corresponding to Stories, also creates statistics 
  2. Connects to github and searches for Test Suites corresponding to Stories, also creates statistics
A Jenkins job is created with configuration as follows


The code uses org.eclipse.egit.github.core and testlink-java-api to connect with github and TestLink respectively


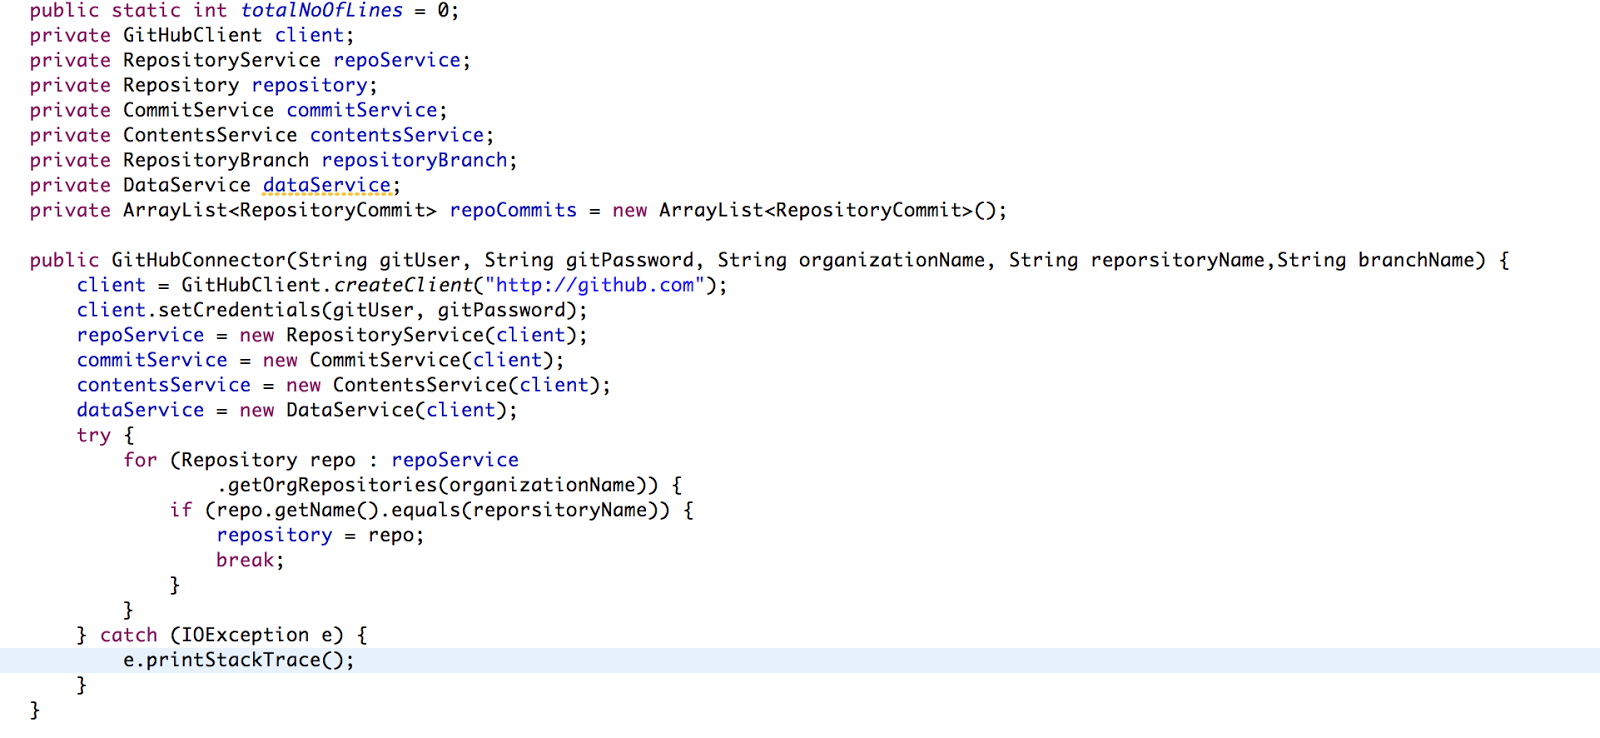
Github Connector is as follows


TestLink Connector is as follows


Above program will also list down stories which needs test cases.


Now you are ready to trace which stories have Test case and which doesn't have. :)

~Yagnanarayana Dande


Automated Testing of Multi Browser Support using SauceLabs and Jenkins/Hudson


               Its not an easy task to run automated tests on multiple browsers and gather results back to a single location. Its not a good option to have your own setup of all Operating System + Browser combinations in a lab if you don't have a dedicated operations team.

             We can use cloud solutions like Saucelabs for this purpose. Saucelabs provides on demand instance of Operating System + Browser. It uses Remove Webdriver concept to run Selenium Tests on these instances.

             You can use following code to start a remote Run


Now create a Jenkins job with configuration as


Now you are ready for your Multi Browser tests. Start a build and test will execute on Saucelabs. 

Once you launch your tests, logon to saucelabs.com and watch the live steaming on how tests are being executed or wait till end to see TestNG report on Jenkins


~Yagnanarayana Dande

Running Selenium Tests on a headless Jenkins Server

                            QA needs to execute their daily Sanity Tests on Jenkins. To run Selenium Tests we need a machine connected to monitor. And if we don't have such an arrangement then we can follow the steps below to run Selenium Tests on a headless Jenkins Server.

Never run daily runs on tools like Saucelabs.com or browserstack as its a costly affair.

1. Install Xvfb on Jenkins Server


yum install xorg-x11-server-Xvfb

2. Install Firefox on Jenkins Server

yum install firefox
3. Install https://wiki.jenkins-ci.org/display/JENKINS/Xvfb+Plugin on Jenkins


4. In you Job, configure as follows


5. When you run the Job, it will create a screen and execute tests on that screen with GUI


Enjoy your daily runs now :)

~ Yagnanarayana Dande

Thursday, March 19, 2015

Integration of TestLink with Jenkins/Hudson to Run Automated Tests


Install the TestNG Plugin on Jenkins


Get API Key from TestLink -> Test Project Management -> API Key


 Go to Jenkins -> Manage Jenkins -> Configure System Add following


Go to Jenkins -> Automation Project -> Build -> Invoke TestLink


Invoke TestLink has 3 Parts

1. Test Link Configuration 
(Using these details Jenkins can get details about Test Cases from TestLink)


 2. Test Execution
(Using this Jenkins execute Test Cases)

3. Result Seeking Strategy
(Using this Jenkins Posts Test Results to TestLink)


Click on Any Build in Jenkins and it shows TestLink Results 


On Right Side Pane of Automation Project, You can see TestLink 


~Yagnanarayana Dande